Tactile Module
Records high-precision, distributed tactile interaction data.
PaXini turns human experience into high-quality, reusable data for Physical AI. Our integrated hardware, software and processing pipeline captures multimodal data—from precise hand and upper-body movements in tabletop tasks to full-body activity in open-world environments.
PaXini's PXCap product series provides a complete, open-architecture hardware system for seamless data collection across diverse environments.
PaXini provides multimodal data spanning multidimensional tactile, multi-view vision, speech, text, proprioception and spatial trajectories, enabling embodied AI to generalize rapidly across scenarios.
PaXini offers In Domian and In the Wild data collection solutions to meet embodied AI's data needs across diverse scenarios.
Comprehensive data diversity for embodied AI development
Records high-precision, distributed tactile interaction data.
Records joint angles from the collection glove and tracks global trajectory data.
Provides synchronized multi-view, high-frame-rate video streams that comprehensively capture the task scenario.
Process multi-view synchronized video streams and annotate corresponding spatial trajectories using estimation algorithms.
Voice data collected before task execution, describing the task.
Structured textual information obtained by converting the collected Voice data.
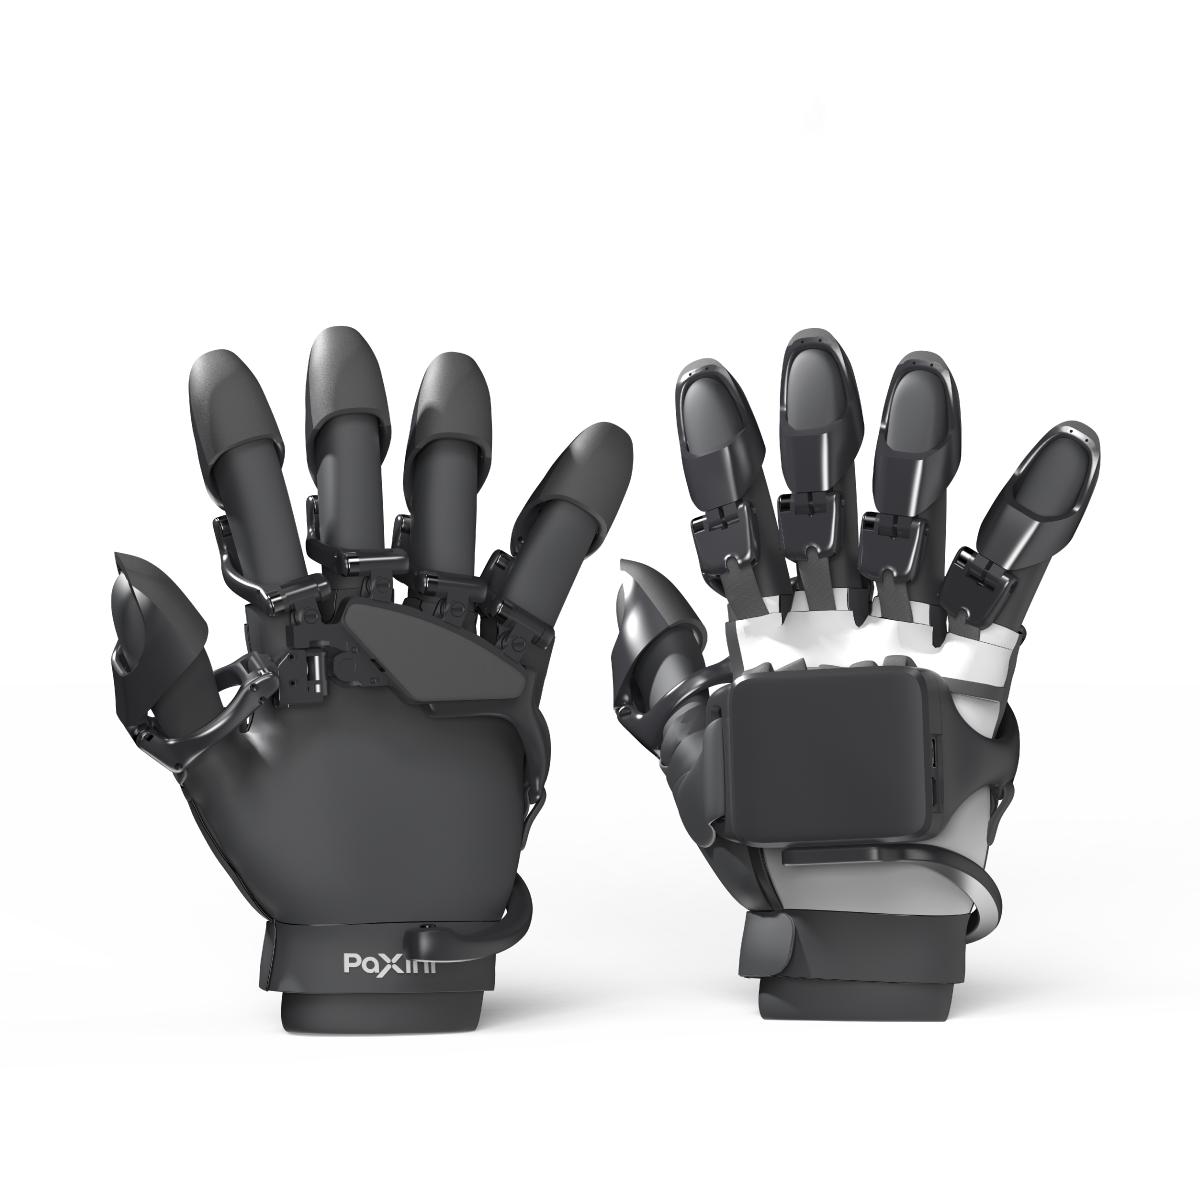
A lightweight data glove for scalable collection, natural operation and comfortable wear. Multidimensional tactile sensing, magnetic joint encoders and wrist camera capture detailed hand-object interactions.
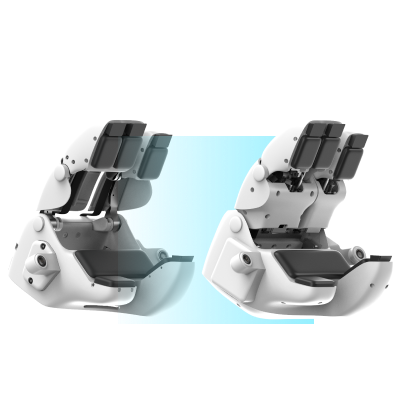
The capture glove and three-finger end effector share a 1:1 physical design, with closely matched sensor layouts and kinematics for direct human-to-robot data mapping.
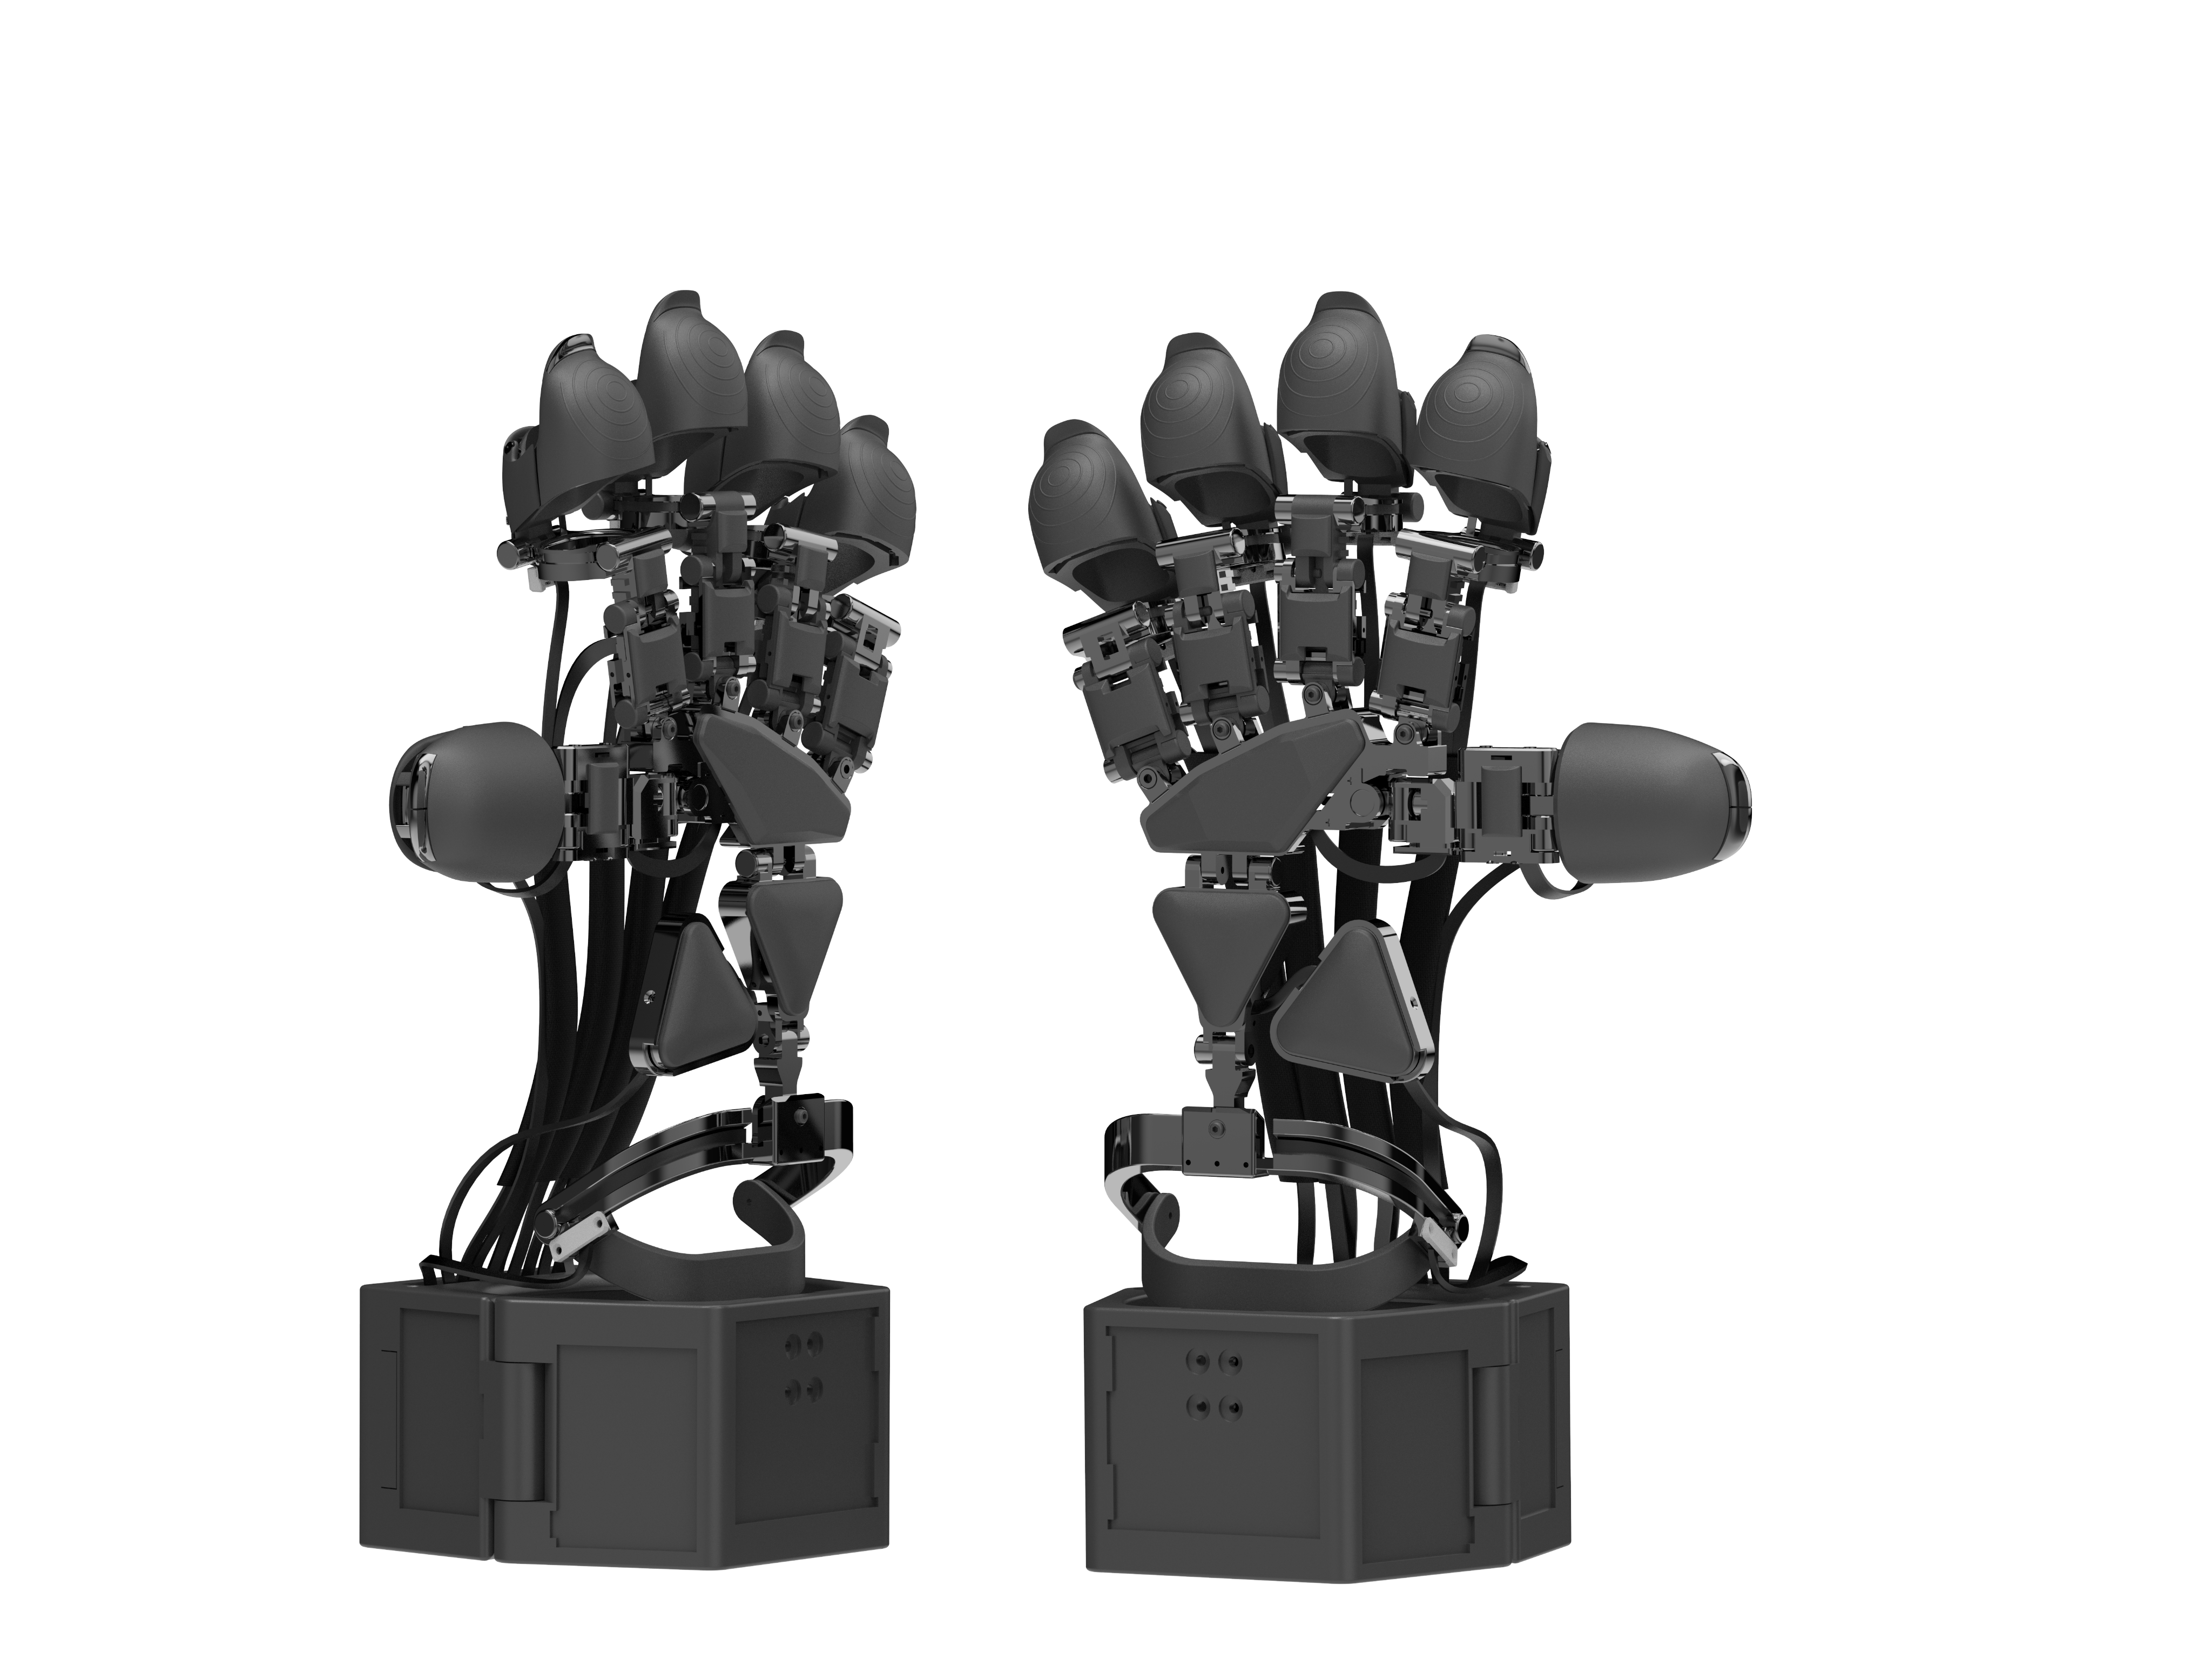
Multidimensional tactile sensors and ultra-compact magnetic encoders provide full-hand coverage for precise capture of joint motion, contact states and force changes.
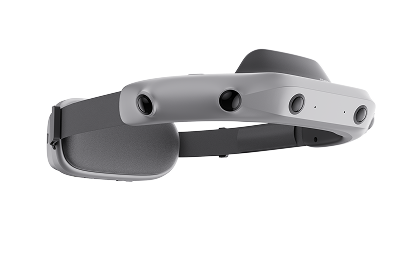
A head-mounted multimodal device combining RGB, IR and high-precision IMU sensing to synchronously capture first-person environmental views, head motion and spatial pose.
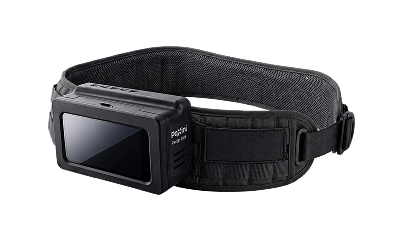
A portable edge computing hub for in-the-wild data collection, integrating computing, power supply and data transfer with on-device parsing, preprocessing, storage and upload.
PaXini's OmniSharing DB is a large-scale, high-quality multimodal dataset captured from real-world human activity, spanning multidimensional tactile data, multi-view vision, speech, text, proprioception and spatial trajectories.


Please download the data sample first, then open Data Demo to view the content.
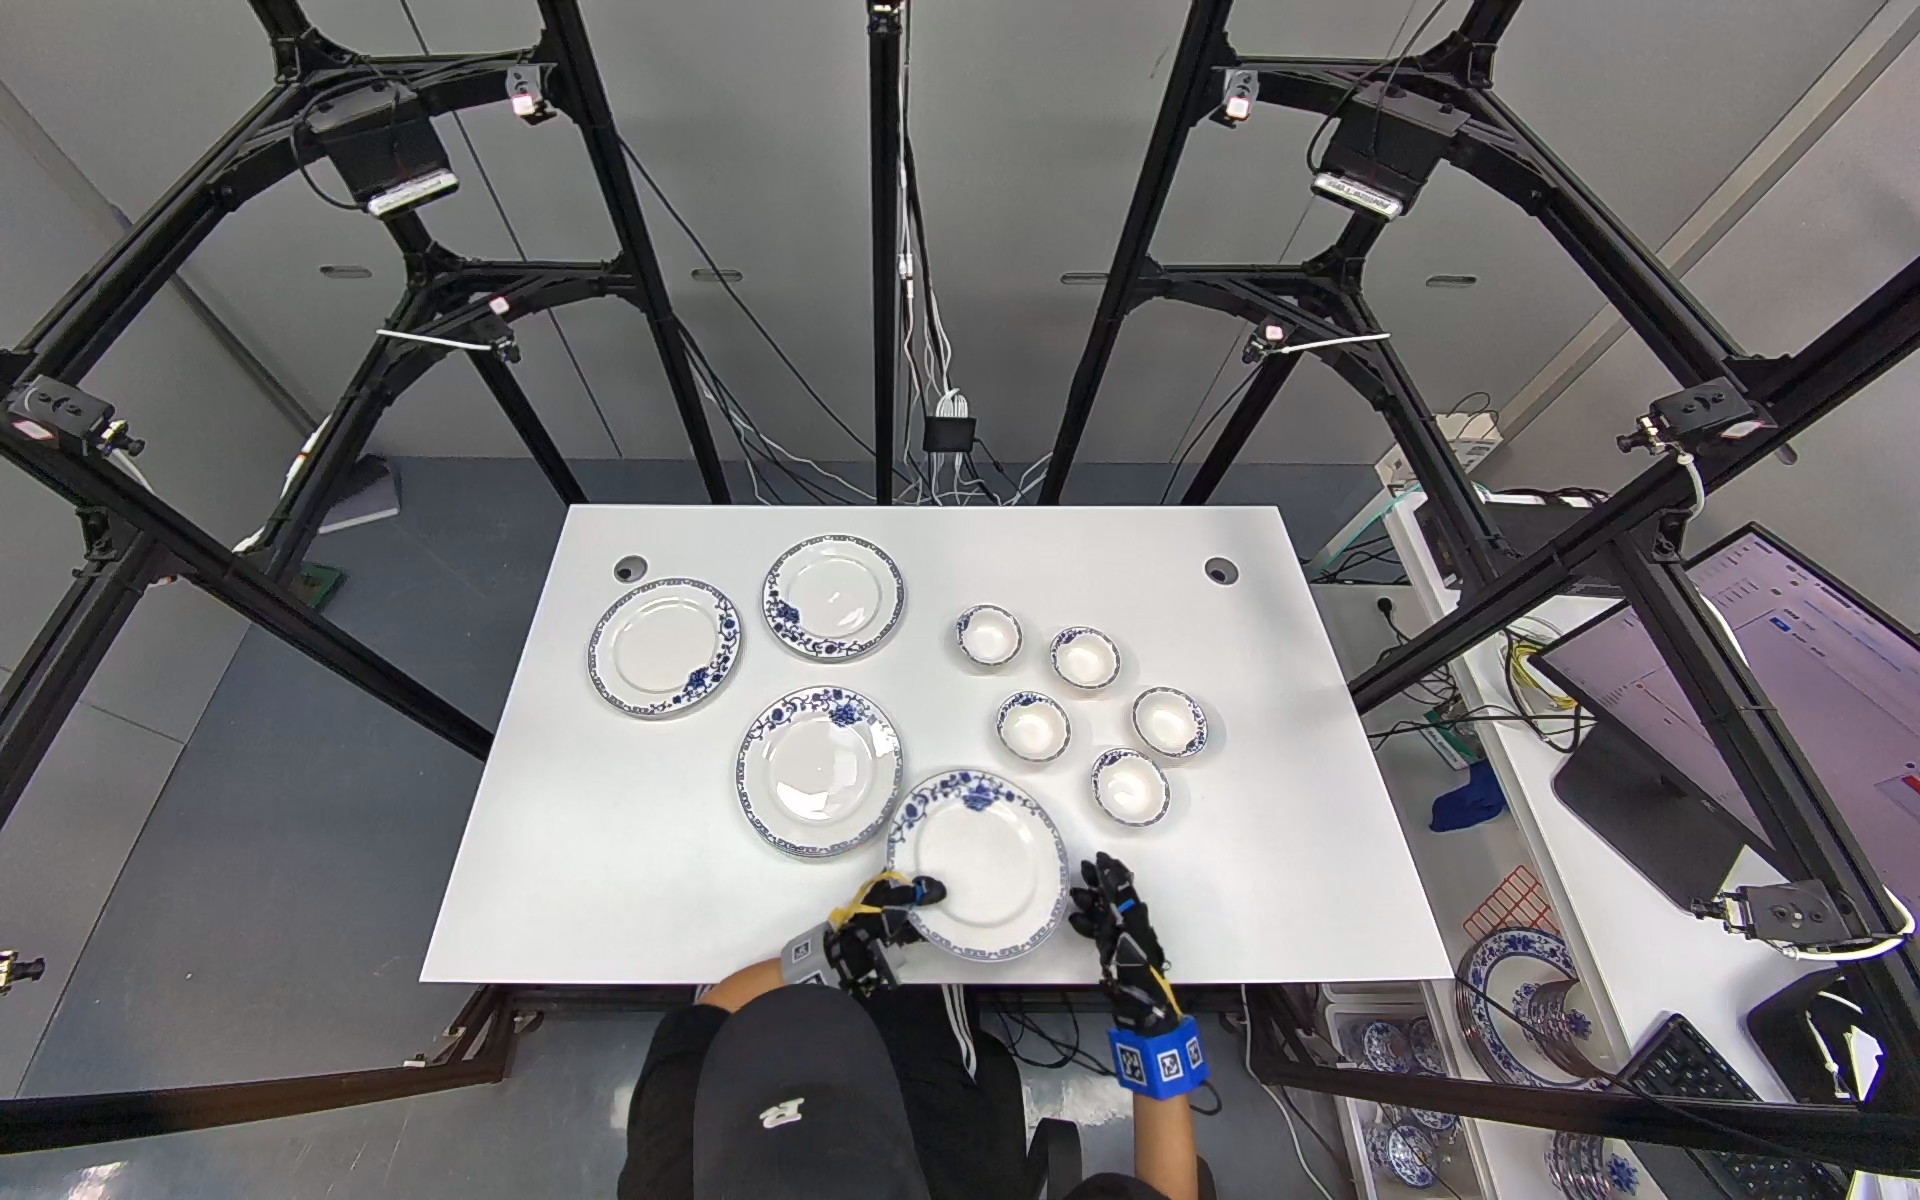
Targeting dexterous manipulation scenarios, human-centric high-precision sampling generates high-fidelity haptic data to close model data loops.
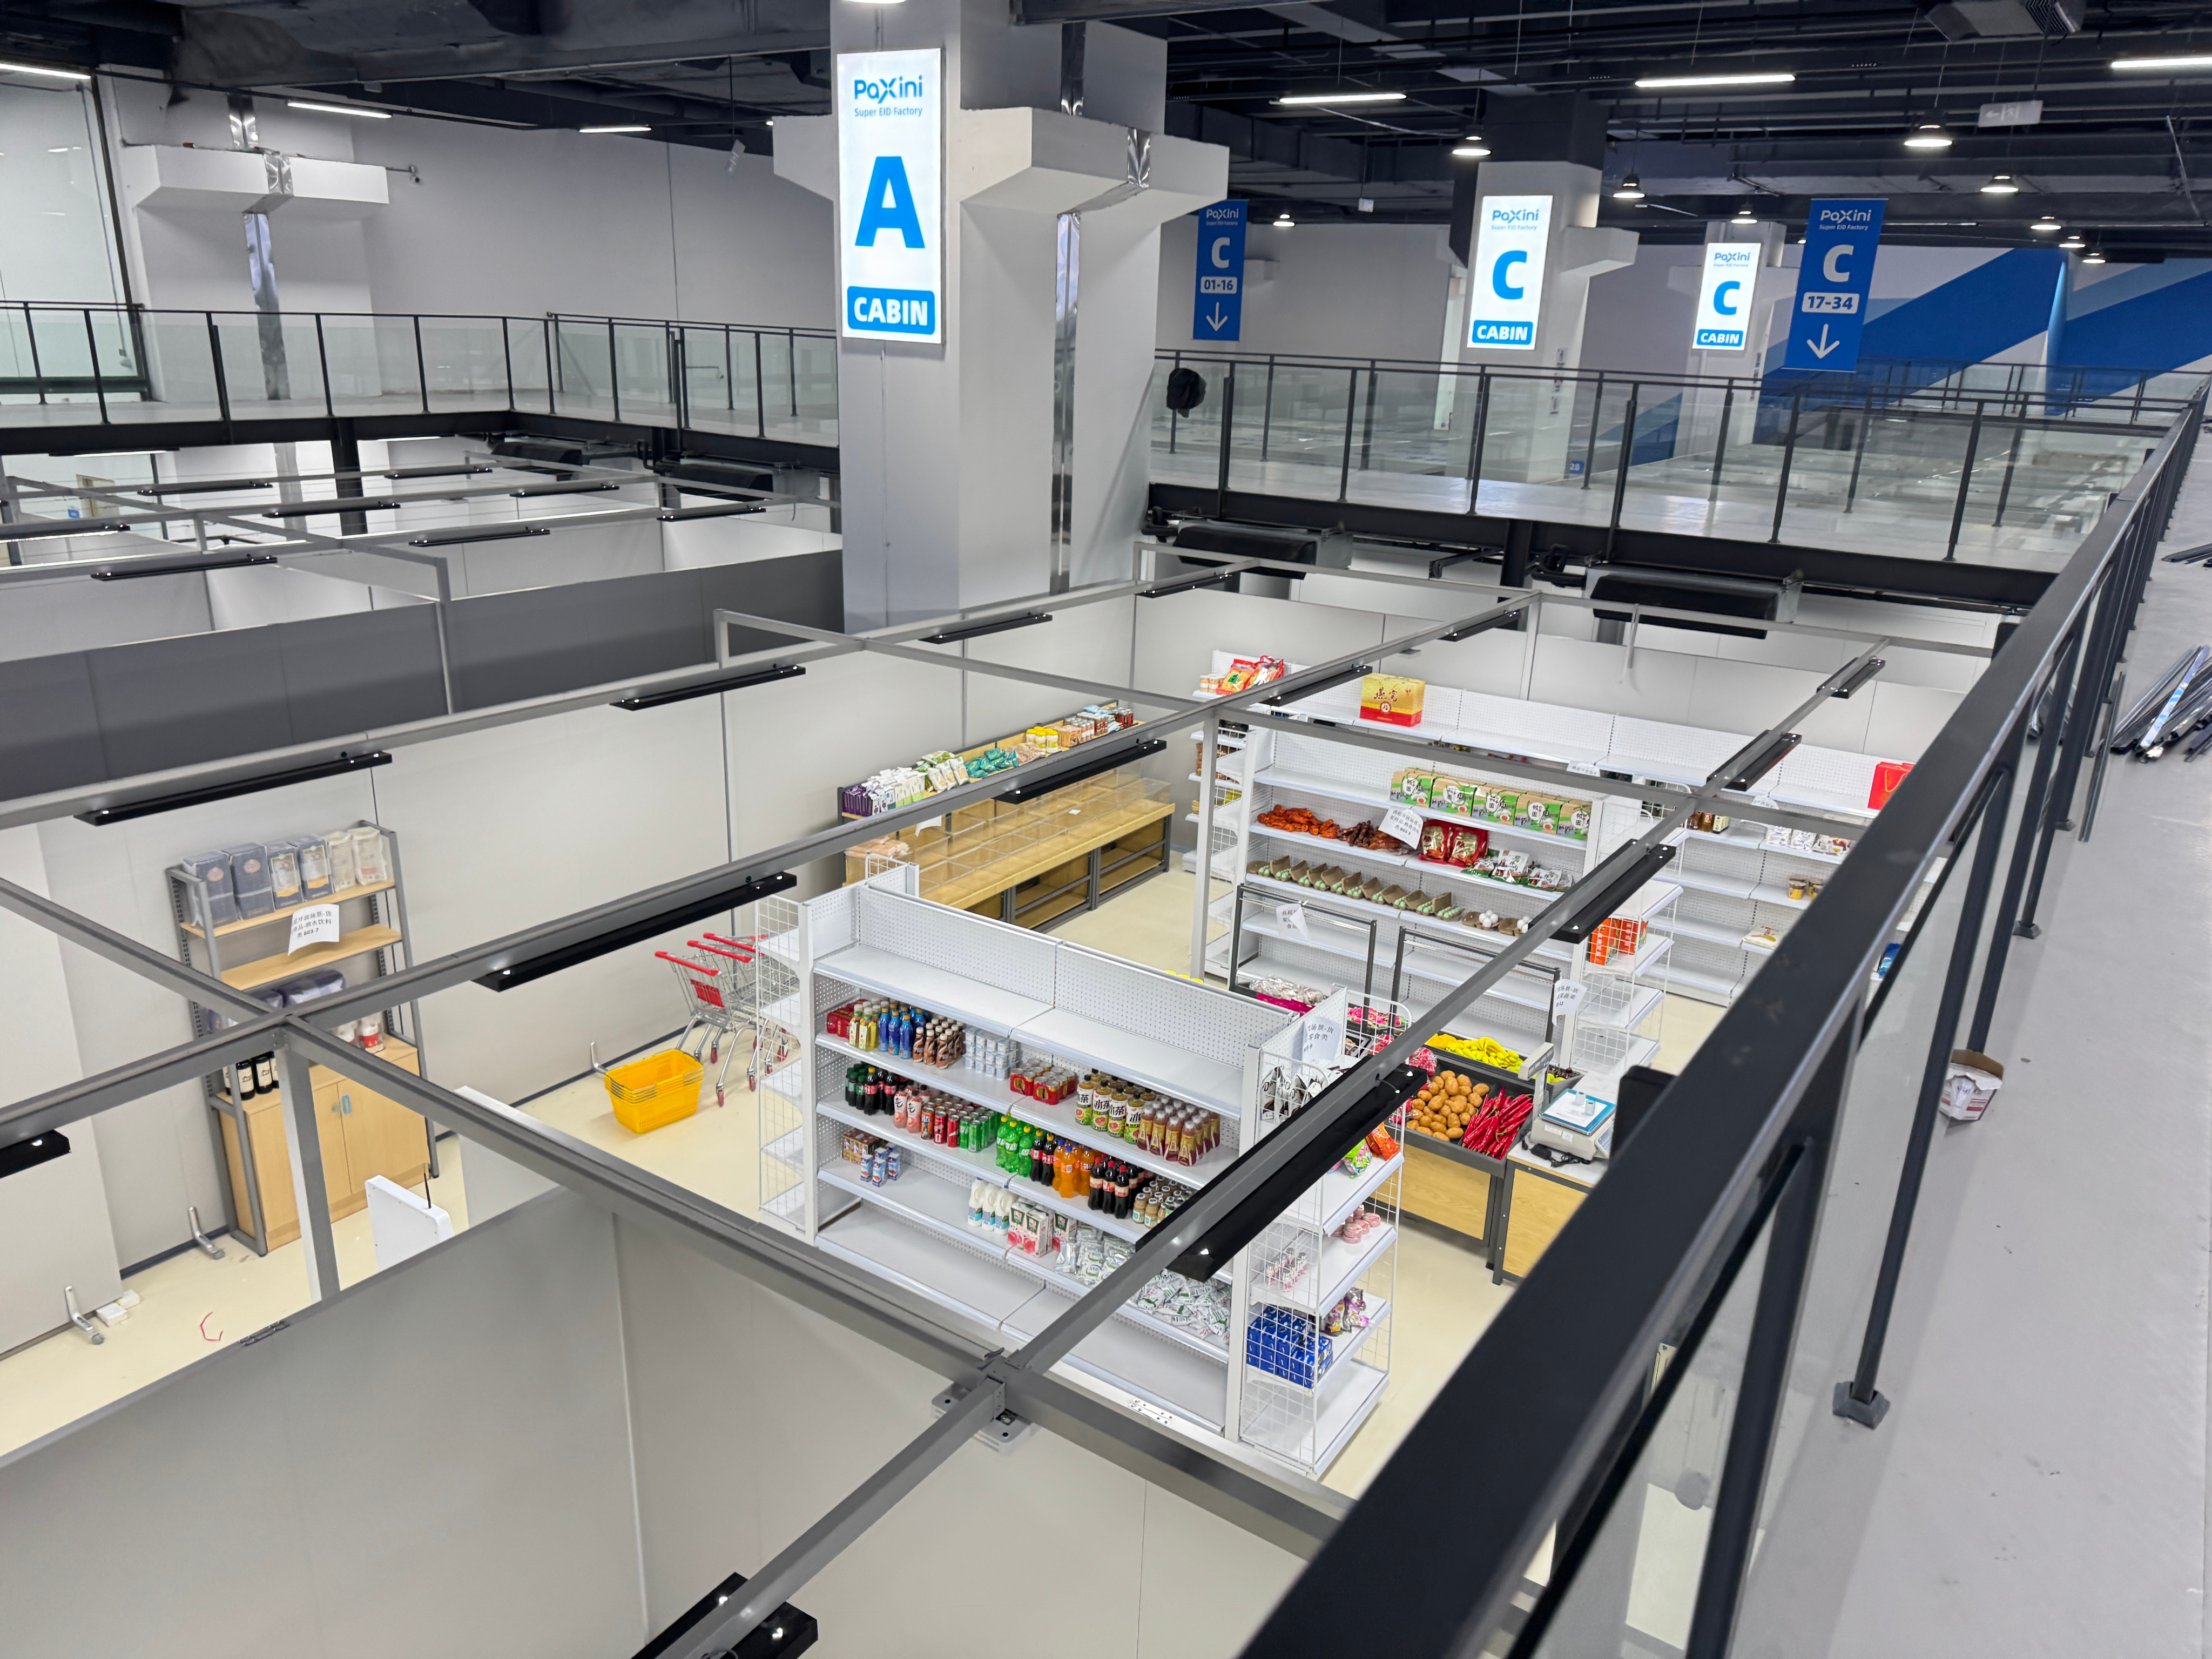
Open collection builds upon In the Wild data collection, relaxes scenario constraints to enrich the model’s environmental awareness, improves long-sequence task planning performance, and evolves iteratively to expand diversified data collection solutions.
Scene Types
15+N
Task Categories
100+
Task Categories
1000+

All Scenes

Office

Home

Healthcare

Medical

Rehabilitation

Logistics

Education

Entertainment

3C Manufacturing

Restaurant

Agriculture

Business

Retail

Disaster Rescue

Automotive

Industrial

Meta Action
Cross-embodiment capabilities and comprehensive data characteristics
Simulation Env
High-Fidelity physical sensing&Sim Platform
Digital Assets
High Fidelity 3D Gasuusian splatting
Multi-Adaptability
High-Accuracy Retargeting&Response
Comparing different data collection approaches for embodied AI
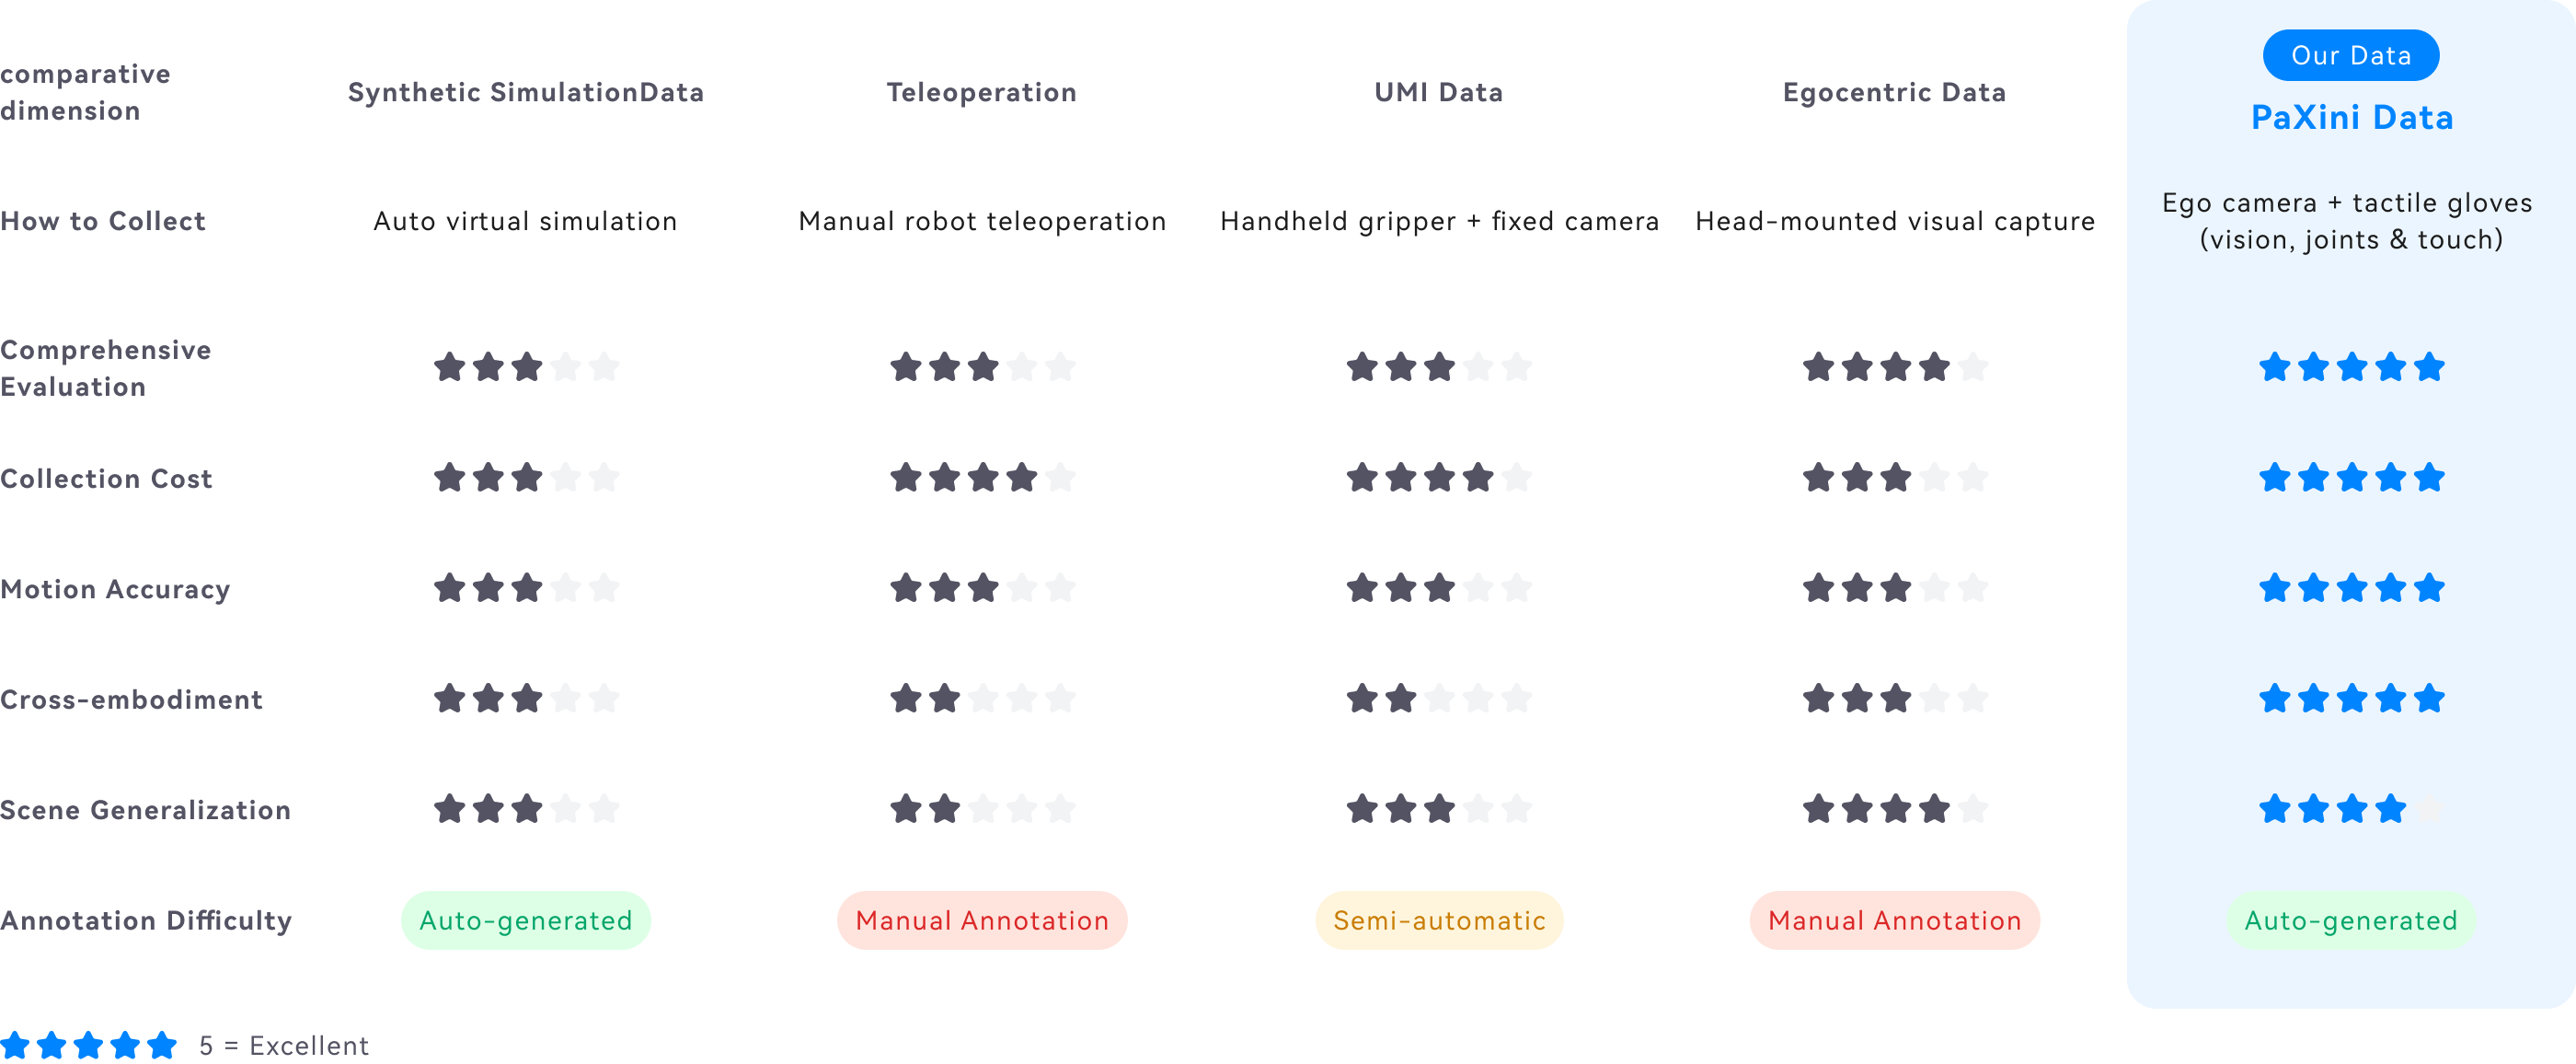
How We Design Our Data Pipeline and Process Data
How We Design Our Data Pipeline and Process Data
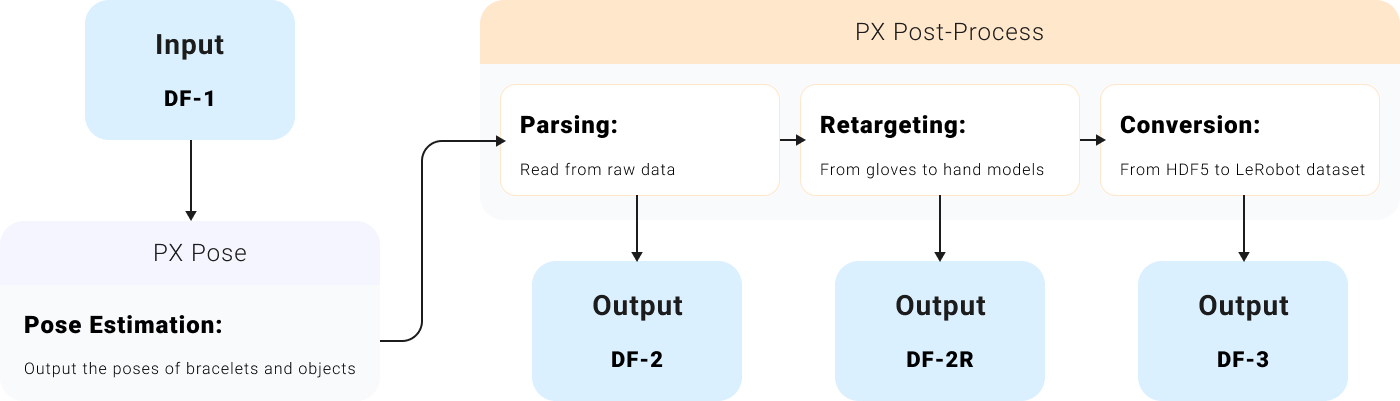
the pose estimation and processing module
DF-1 format parses RGBD camera information and aligns multi camera temporal data to provide input for pose estimation.
Binocular infrared depth estimation, wristband automatically detects pose, and objects need to be manually labeled with masks to estimate pose.
Parses and converts after all raw data is obtained
Processes the raw data output from PX Pose and generates the DF-2 data format.
Retargets DF-2 data to the embodiment and outputs DF-2R.
Processes DF-2R data and exports it in the LeRobot data format.
Hierarchical dataset organization across all processing stages
The overall input: raw data after preprocessing and quality inspection
1st output: DF-1 with encoder and tactile data parsed; adds bimanual and object poses; includes both action and observation
The observation layer in DF-2 and DF-2R is the state data in the episode, while action is one frame behind observation. To ensure both arrays have equal length, the last frame in action is repeated.
2nd output: DF-2 retargeted to a dexterous hand model
The observation layer in DF-2 and DF-2R is the state data in the episode, while action is one frame behind observation. To ensure both arrays have equal length, the last frame in action is repeated.
3rd output: converts DF-2R to the LeRobot dataset format; can be used for VLA model training
Full-Pipeline Real2Sim2Real Data Capabilities and Models for Closing the Data Loop
PaXini · Beijing
+86 755 2357 4593
PaXini · Shenzhen
+86 755 2357 4593
PaXini · Shanghai
+86 21 5456 1536
PaXini · Tianjin
+86 22 8241 1882
PaXini · Wuhan
+86 27 8309 0662
PaXini · SuQian
+86 527 8080 6580
mkt@paxini.com China
sales_global@paxini.com Overseas
hr@paxini.com